We integrate practical AI pipelines and task automation into your product to process data and remove repetitive manual work.
- Capabilities
- 06
- Delivery phases
- 04
- Core technologies
- 05
WeimplementAIintegrationswheretheydeliverclearfunctionalvalue:vectorsearchengines(pgvector/Pinecone),automateddocumentprocessing,andbackgroundworkflowpipelines.Everybuildincludesevaluationtests,errorhandling,andstrictpromptguardrails.
Scoped in, not bolted on. Every engagement covers these from the first sprint.
LLM API integrations (OpenAI / Anthropic)
Document & unstructured data extraction
Background task queues (Celery / BullMQ)
Retrieval-Augmented Generation (RAG)
Automated customer workflow routing
AI output evaluation & guardrails
Chosen for longevity, not hype
- Node.js
- TypeScript
- PostgreSQL
- AWS
- Docker
No black boxes. You see the plan, the pull requests and a working build at the end of every phase.
Floor 01
Workflow evaluation
We identify manual data processes where AI integration delivers quantifiable time savings.
Floor 02
POC & accuracy testing
We build a working proof-of-concept to measure model accuracy before full integration.
Floor 03
Production deployment
We integrate AI endpoints into your main application with rate limiting and fallback logic.
Floor 04
Monitoring & tuning
We track token usage, response latency, and output precision post-launch.
We typically fine-tune or integrate proven foundation models, which provides faster deployment and lower costs than training from scratch.
We build automated validation pipelines and fallback logic into every AI feature to prevent hallucination issues.
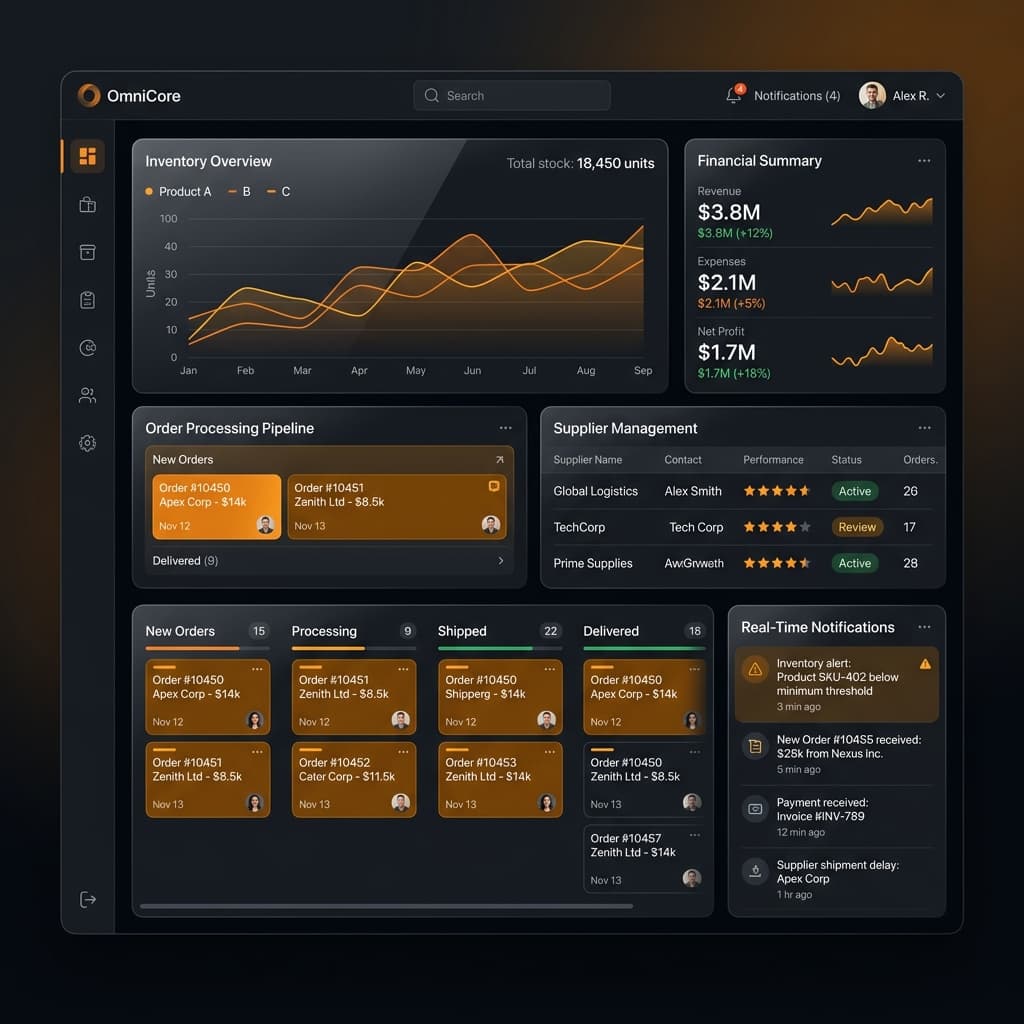
Yes, we build secure data extraction layers connecting LLM pipelines directly to your database or storage buckets.
Tell us about your roadmap. You'll hear back within 24 hours with a clear technical plan, and no sales pressure.